Start with the axes and bins
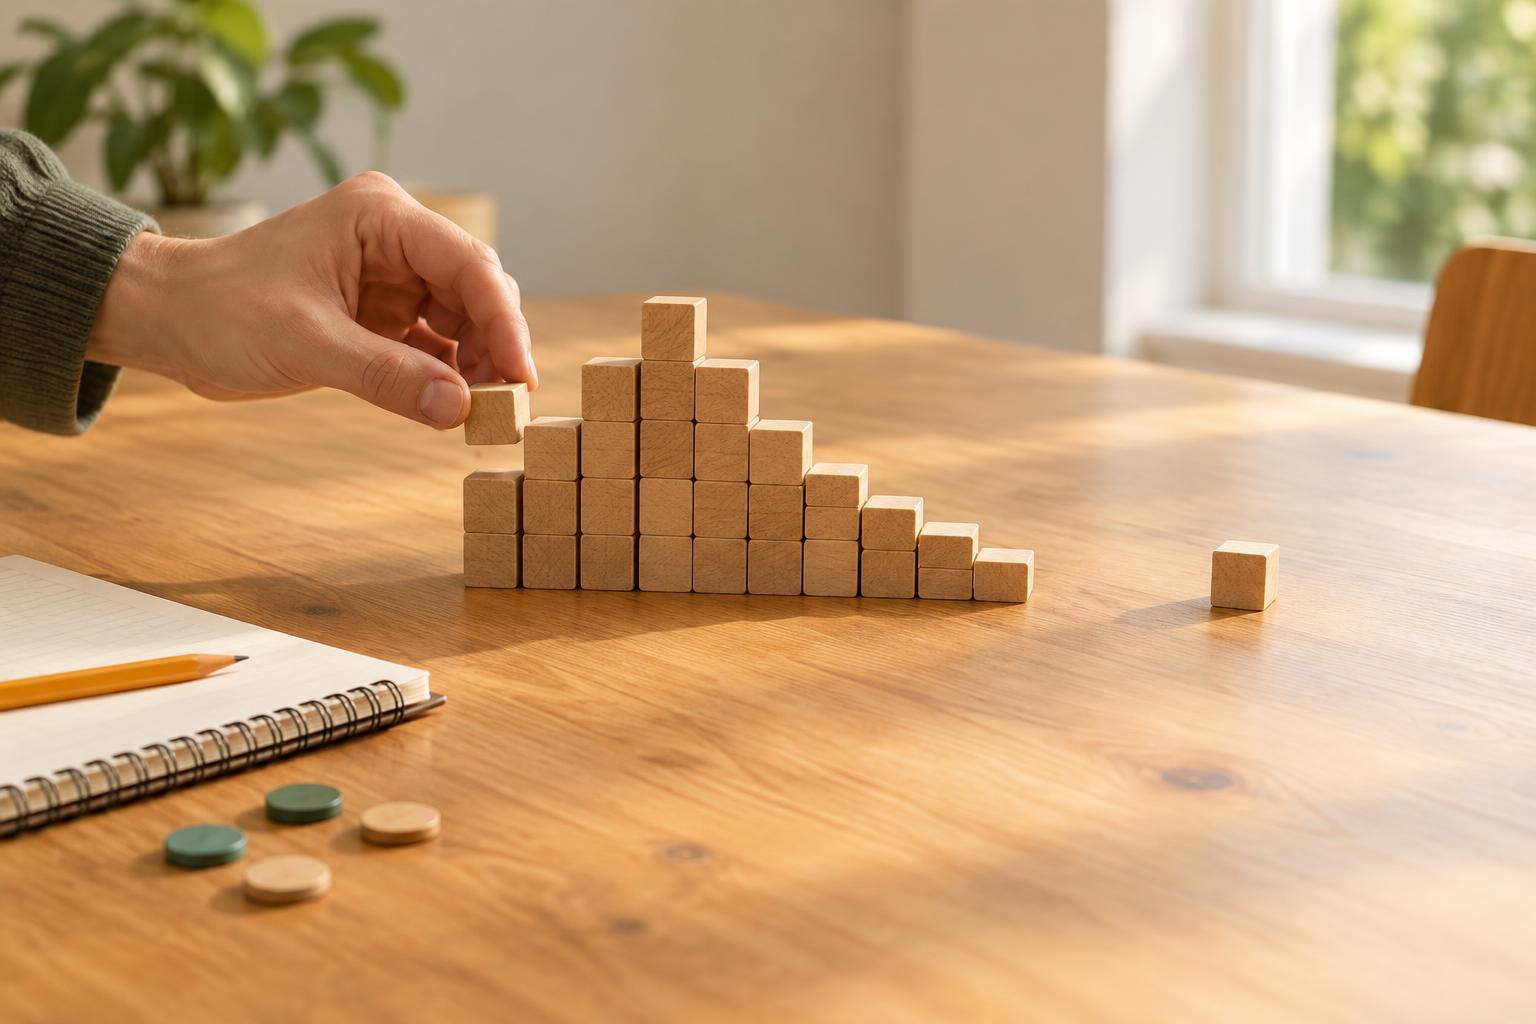
A histogram shows how numerical observations are distributed. The horizontal axis groups values into intervals called bins; the vertical axis usually shows how many observations fall in each bin. If a class records the time students spend on an exercise, one bin might contain times from 10 minutes up to, but not including, 15 minutes. A taller bar means more recorded times fell in that interval.
Read the axis labels before describing the pattern. Check what was measured, its units, the range shown, and whether the vertical axis reports counts, percentages, or another measure. Unlike a bar chart of categories, a histogram arranges numerical intervals in order. Its bars normally touch because the intervals cover adjacent parts of a numerical scale. A gap can indicate a range containing no observations.
Also check whether the bins have equal widths. With equal-width bins, comparing bar heights is a straightforward way to compare frequencies. If widths vary, height alone can mislead: the area of a bar may represent the frequency instead. Look for a label such as “density,” and avoid comparing unusual bin widths as though they were identical.
Describe the overall shape
First, step back from individual bars. Where are most values concentrated, and how widely do they spread? A histogram with one clear high region is often described as unimodal. One with two distinct high regions is bimodal. A fairly even spread across the displayed range may be described as roughly uniform. These words summarize what the picture suggests; they do not explain why it looks that way.
For example, imagine a histogram of exercise times with most observations between 15 and 25 minutes and fewer on either side. Its center is somewhere near that busy region, even if the exact average cannot be read from the chart. If the same histogram has peaks around 15 and 35 minutes, consider whether it combines different kinds of exercises or groups of students. That is a question to investigate, not a conclusion the histogram proves.
Pay attention to clusters and gaps as well as peaks. A gap might reflect a real separation, a small dataset, or simply the chosen bin boundaries. When describing a histogram, use measured language such as “most values appear between 15 and 25 minutes” rather than claiming a precise proportion that the display does not provide.
Find the direction of skew
Skew describes a distribution whose values stretch farther on one side than the other. To name its direction, look at the long, thin tail rather than the side with the tallest bar. A right-skewed distribution extends farther toward larger values; a left-skewed one extends farther toward smaller values. If the two sides have similar shapes, you might call it roughly symmetric.
Suppose most exercise times fall between 10 and 30 minutes, but a few extend toward 60 minutes. The tail points right, so the histogram is right-skewed. In another example, if most quiz scores are high and a smaller number extend toward low scores, the tail points left. Neither description says that the high or low values are errors.
Skew matters when choosing a useful summary. A few extreme values can pull an arithmetic mean toward the tail, while the median—the middle observation when values are ordered—is less affected. A histogram cannot always give you either statistic exactly, but it can alert you to ask for both rather than relying on one number to describe every distribution.
Treat apparent outliers as questions
An outlier is a value unusually far from the main body of observations. On a histogram, it might appear as a lone bar beyond a gap or as a small bar at the end of a long tail. It is better to call this a possible outlier until you can inspect the underlying values: binning can conceal how far apart individual observations really are.
Consider a hypothetical set of exercise times clustered below 30 minutes with one record near 90 minutes. That record might represent an unusually long session, a pause that was included in the timing, or a data-entry mistake. The histogram alone cannot distinguish among these possibilities. Check how the measurement was defined and collected before excluding anything.
Sample size also matters. One isolated value among a handful of observations looks different from one among hundreds. An unusual observation can be important information rather than a nuisance, especially if your aim is to understand the full range of experiences.
Check whether the display changes the story
A histogram is a summary, and its appearance depends partly on design choices. Wide bins can hide gaps or combine nearby peaks; narrow bins can make ordinary variation look jagged. If possible, view the data with more than one reasonable bin width. A pattern that persists is easier to describe with confidence than one that appears only under a particular setting.
Before comparing two histograms, check that they use compatible axes and bin boundaries. Counts may be misleading when the groups have different numbers of observations; percentages or comparable density scales can make their shapes easier to compare. Do not assume two charts use the same scale just because they sit side by side.
A useful reading brings these checks together: name the variable and units, locate where values cluster, describe any skew or gaps, and flag possible outliers for follow-up. Then distinguish what the histogram shows from what you still need to learn. It can reveal patterns worth investigating, but it cannot, by itself, establish their causes.