Start with the question: What does one row represent?
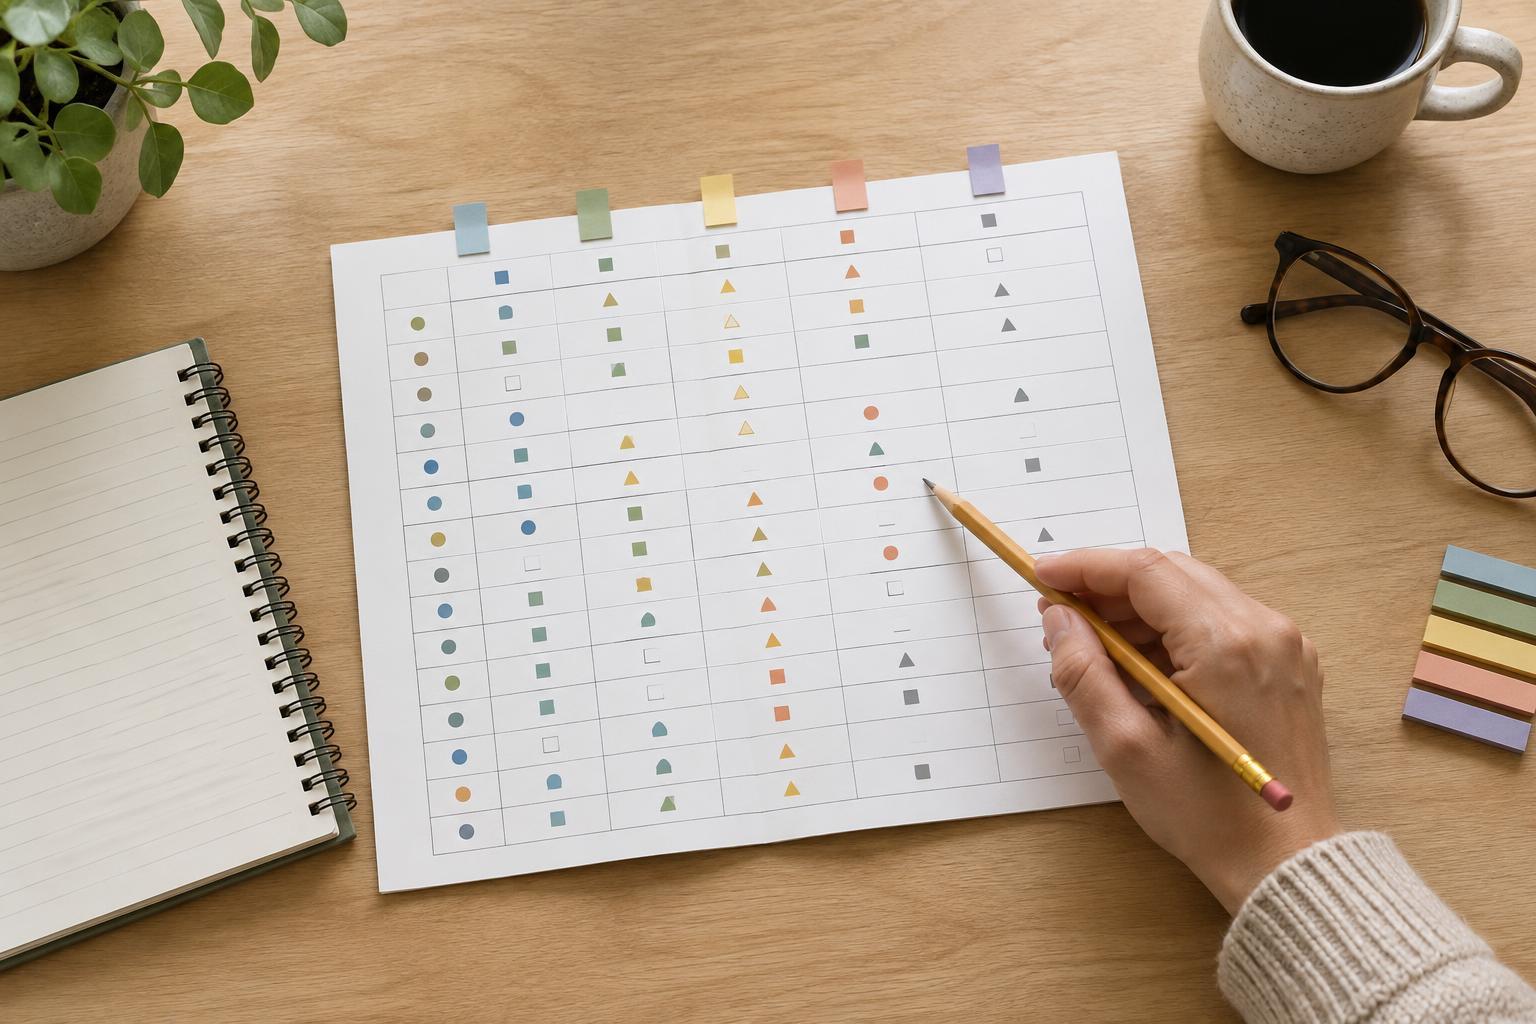
Imagine a spreadsheet about attendance at a series of workshops. Its first columns are participant_id, workshop_name, session_date, and attended. Before counting anything, ask what a single row represents. Is it one participant, one workshop, or one participant at one workshop session? The answer defines the dataset’s unit of observation: the particular thing or event recorded on each row.
If each row records one participant at one session, the same participant may appear many times. Counting rows would tell you how many participant-session records there are, not how many distinct people attended. A question about people requires a different count from a question about sessions. Writing a simple sentence such as “Each row represents one participant’s record for one workshop session” is a useful first step.
Read columns as descriptions, not just labels
Columns hold the attributes recorded for each observation. In the workshop example, session_date describes when a session took place, while attended records an outcome for a participant at that session. A column name is only a clue, however. A column called score might contain a test result, a satisfaction rating, or a category assigned by an organizer. Look for a data dictionary, notes, or other documentation that defines the field.
Check what kind of value each column contains and how it is represented. Dates may be stored as text; an attendance field might use “yes” and “no,” 1 and 0, or several categories. Numbers also need units: a duration of 45 means little until you know whether it is measured in minutes or seconds. Identifiers such as participant_id may consist of numbers, but they are labels rather than quantities to average.
Also ask which columns identify a row uniquely. If a participant can attend only one instance of a given session, participant_id and session_date might identify a record together. But that assumption fails if two workshops occur on the same date. Checking whether a proposed identifier actually distinguishes rows can expose misunderstandings about the dataset.
Understand what an observation does and does not tell you
An observation is a recorded instance of the unit you have identified. It is not necessarily a person, and it is not automatically an independent piece of evidence. Ten records for one participant across ten sessions describe repeated activity by that person. They should not be casually presented as ten different participants.
The level of detail in a dataset is sometimes called its grain. A participant-session dataset has a finer grain than a table with one row per participant and a total number of sessions attended. The summary table can answer questions about totals per person, but it may no longer show which sessions those people attended. Conversely, a session-level table with one row per workshop date may show total attendance without identifying individual participants. Before using a dataset, check whether its grain matches the question you want to answer.
Some datasets use different layouts for the same underlying information. A table with separate columns for attendance in January, February, and March is often called wide. A table with month and attendance columns, plus multiple rows per participant, is often called long. Neither layout is inherently more accurate. What matters is recognizing what a row means in the layout you have.
Check missing values, duplicates, and scope
A blank cell is not necessarily a zero or a “no.” In the attended column, a blank might mean the status was not recorded, the participant had not yet responded, or the field does not apply. Those possibilities lead to different interpretations. Look for documentation, compare related fields, and keep the meaning of an unexplained blank uncertain rather than silently assigning it a value.
Repeated rows deserve similar care. Two identical-looking records might be an accidental duplicate, or they might describe separate events whose distinguishing details were left out. Check the intended unit of observation and any available identifiers before removing records. It also helps to examine the dataset’s scope: which participants, sessions, locations, or time periods are included? An attendance rate calculated from the table can only describe the records it covers.
Use a short reading routine before calculating
First, describe one row in a sentence. Second, scan the column definitions, units, and permitted values. Third, find out whether identifiers are unique at the level you expect. Fourth, inspect a handful of rows, including blanks and repeated identifiers. Finally, state what you plan to count and what belongs in the denominator.
For example, to report the share of recorded participant-session opportunities marked attended, count records marked attended and divide by the relevant participant-session records, explaining how unknown statuses were handled. To report the share of participants who attended at least once, count distinct participants instead. Both calculations can be reasonable, but they answer different questions. Reading the structure first helps you choose the one you mean.